

- Navigation: Settings > AI Configuration
- Required role: Owner or Admin
LLM providers
The Agent Platform is provider-neutral. Agents can use models from multiple LLM providers, and you can switch between them without changing agent definitions.- Navigation: Settings > AI Configuration > LLM Providers
- Required role: Owner or Admin
How model resolution works
Model configuration follows a layered approach. When the runtime executes an agent, it resolves the model through a five-level priority cascade, stopping at the first match:
If no model is resolved at any level, the request fails with a clear error. The platform never falls back to a hard-coded default.
Fallback chains
Configure fallback models to handle provider outages or rate limits. When the primary model fails (timeout, rate limit, or provider error), the runtime automatically retries with each fallback in order. The agent receives a response regardless of which model served it, and analytics track which model was used. Configure fallback models:- Go to Settings > AI Configuration > Models.
- Select a registered model.
- In the Fallback section, add one or more fallback models in priority order.
- Click Save.
Context window management
The runtime automatically manages the context window to stay within model limits:- Tool result compression - Large tool results are compressed before being added to the conversation.
- Prior turn truncation - Tool results from previous turns are replaced with short placeholders.
- Conversation compaction - When conversation history grows beyond the Compaction Threshold, older messages are summarized to reduce token usage while preserving context.
Cost and token tracking
Every LLM call tracks token usage and estimated cost, broken down by agent, project, model, and time period:Credentials
The Credentials tab lists all provider credentials registered in your workspace, grouped by provider. Each credential card shows the name, provider, creation date, and the number of models using that credential. Add a credential:- Go to AI Configuration > LLM Providers > Credentials.
- Click + Add Credential.
- Enter a Name (for example, Production OpenAI), select a Provider, and enter the API Key.
- Click Add Credential.
API keys are encrypted at rest and never displayed in plaintext after the initial entry.
Model catalog
The Model Catalog tab lists all models registered in your workspace. Each row shows the provider, model name, model ID, linked credentials, and status. Workspace tier defaults A model becomes a workspace default only when a workspace admin selects it here for a routing tier. It must be ready, active, inference-enabled, and backed by a Workspace-shared connection. Configured models may remain without a default, and a tier default never grants project access. Defaults are one-per-tier workspace catalog metadata - they don’t grant or automatically apply project access. Each project must separately select an authorized binding in Selected models (see Project Access). For each tier (Fast, Balanced, Powerful, Voice), the panel shows the tier’s intended use, its associated operation tags (for example Fast: Extraction, Validation, Tool selection), and a Workspace default dropdown to assign a model. Below the tier defaults panel, the model table lists every registered model with its provider, model name and ID, connections, a star (favorite) icon, and Ready status. Add a model from the catalog:- Go to AI Configuration > LLM Providers > Model Catalog.
- Click + Add Model, browse or search for a provider model.
- Review and configure the available model settings.
- Click Add to Workspace.
- Go to AI Configuration > LLM Providers > Model Catalog.
- Click + Add Model, then select the Custom Model tab.
-
Fill in the following fields:
Available fields in the Custom Model dialog depend on the selected model and provider - not every model exposes Temperature or Max Tokens.
- Click Add to Workspace.
-
Click + Add Key to connect a credential. In the Add Connection dialog, choose one of two connection methods:
Optionally check Set as primary connection, choose Connection visibility (default: Workspace-shared - the compatibility-safe default; restrict a connection only when its project allowlist is known), then click Create Connection.
- Each connected credential is listed with its name, type (for example API Key), and whether it’s the Primary connection. Click Test to verify the connection, or the delete icon to remove it.
- Change a connection’s Connection visibility at any time and click Save access to apply.
Select the Reasoning Effort level from the dropdown to control how much reasoning the model applies before responding.
Capabilities
Enable supported capabilities: Default for Tier, Tools, Vision, Streaming, and Realtime Voice. Available capabilities are model-dependent - unsupported ones appear disabled.
Click Save to apply changes, or Delete to remove the model from the workspace.
Model tiers
Tiers decouple agent definitions from specific model choices. Agents reference tiers, and the platform resolves the tier to a specific model at runtime:
Project-level tier overrides:
Projects inherit the workspace’s model configuration but can customize how tiers map to operations. Go to Project > Settings > LLM Configuration to override tiers per operation:
Overrides apply only to the current project. Other projects continue using workspace defaults.
Project Access
The Project Access tab inspects and manages a single project’s model bindings and feature routing, from the same authoritative configuration used by Studio and Runtime.- Select the project from the Project dropdown.
- The tab has three sub-tabs: Selected models, Feature config, and Resolution diagnostics.
Secret values and binding identifiers are never shown on this page.
- Model access rollout banner - indicates whether the project uses selected model bindings only, or has unresolved legacy references.
- Imported default model unavailable banner (when applicable) - shows a legacy project default that was imported but can’t run until its workspace model and credential are configured, tagged Project default and Workspace model not configured.
- Selected models / Eligible models counts.
- The Selected models list shows each bound model with its provider, connection type (for example
Workspace-shared), status (for example Ready), and whether it’s the Project default. Click the X to remove a model. - Click + Add models to open Add models from the workspace catalog. Search, then click Add next to any workspace-shared or project-restricted connection - each entry shows its provider, connection type, and readiness (for example Not tested or Ready).
- Use the Project default (this project only) dropdown to set which selected model is this project’s default, then click Save selection.
- Toggle Per-operation routing to switch between “every feature follows its tier” (off) and per-feature overrides (on).
-
Banners:
- Some features need attention - lists features whose model binding needs a fix.
- Model access rollout - same as in Selected models.
- Catalog features not available for execution - lists newer catalog features not yet executable (for example: Query rewriting, Retrieval reranking).
- Tier bindings - Fast, Balanced, Powerful, and Voice cards, each showing the feature count on that tier, a model dropdown (or No model bound), and a short description of the tier’s intended use. Each tier draws only from this project’s selected models.
-
Below the tier bindings, the full feature list is grouped by category:
Each feature row shows an enabled checkbox, its name, description, and operation code; a tier-or-override control (a tier dropdown, or Override with a model to pin a specific model, plus a Why this model? link explaining the resolution); which model it Resolves to; the source it came From (for example Project default); and its Status (for example Ready).Overrides can use selected project bindings only.
- Click Save feature config to apply changes.
-
Choose the Resolution context to preview - for example Project working configuration, or a specific deployment (for example
dev · 1.0). -
The table lists each Operation (for example Extraction, Validation, Tool selection, Response generation) with:
Click View resolution details on a row to see the full precedence trail - for example whether a Deployment override, Project feature override, Project model selection, or Workspace tier default was applied.
Troubleshooting
Model Pricing
Manage workspace-level LLM pricing overrides and inspect inherited project and platform prices.- Navigation: Settings > AI Configuration > Model Pricing
- Required role: Owner or Admin
- Go to Settings > AI Configuration > Model Pricing.
- Click + Add pricing.
- In the Add workspace pricing dialog, enter:
- Click Save pricing.
- Go to Settings > AI Configuration > Model Pricing.
- Click Import.
- In the Import workspace pricing dialog, provide the rows either by:
- Clicking Choose File to upload a CSV or JSON file, or
- Pasting JSON rows or CSV with headers directly into Import content.
- Optionally, check Allow overlapping windows to permit pricing rows with overlapping effective-date ranges.
- Click Preview import to validate the rows before committing.
- Click Commit import to apply the previewed rows as workspace overrides.
Arch
Arch is the AI Architect component of the Agent Platform. It manages the model and credentials used for agent specification generation and chat-based orchestration.- Navigation: Settings > AI Configuration > Arch
- Required role: Owner or Admin
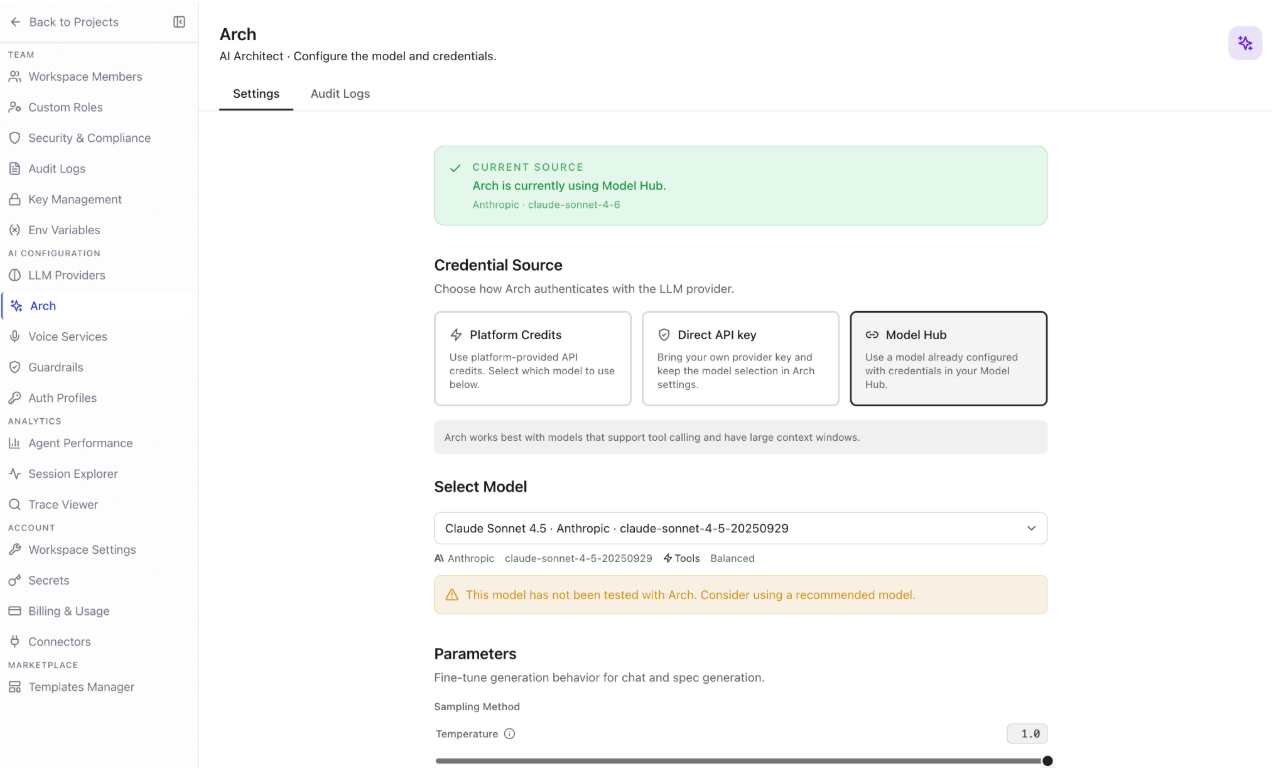
Settings
Current source: The Current Source banner displays the active credential source and model Arch is currently using, for example Model Hub · OpenAI · gpt-5.2. Credential source: Choose how Arch authenticates with the LLM provider:Arch works best with models that support tool calling and have large context windows.
Click Save Changes to apply updates.
Audit logs
The Audit Logs tab shows Arch session activity for the selected time range, including cost, error count, and a browsable session list. Summary metrics:
Sessions list:
The list displays all Arch sessions. Use Has Errors to show only sessions with errors, or Today to show only today’s sessions. Each session row shows the session ID, timestamp, number of turns, and current phase. Click a session to view the full execution flow in the detail panel.
Voice services
Voice Services manages credentials for speech-to-text (STT) and text-to-speech (TTS) providers that power voice-enabled agent interactions.- Navigation: Settings > AI Configuration > Voice Services
- Required role: Owner or Admin
Voice testing requires at least one STT (ASR) provider and one TTS provider configured; any supported provider combination works. For Realtime Voice, configure a realtime model (S2S).
Configure a provider
- Go to Settings > AI Configuration > Voice Services.
- Find the provider you want to configure and click Configure.
- Enter the provider credentials in the configuration dialog.
- Click Save.
BYO custom speech providers
Tenant-scoped custom STT/TTS adapters available to voice pipeline channels. Use this when you want to host your own speech recognition or synthesis adapter instead of a built-in provider. You write and run the adapter; the platform routes call audio to it. Add a BYO speech provider:- Go to Settings > AI Configuration > Voice Services > BYO custom speech providers.
- Click + Add provider.
- Enter the provider details:
- Configure the Speech-to-text (ASR) and/or Text-to-speech adapters (see below).
- Click Save.
Use the Adapter contract panel to open the STT or TTS contract while filling in URLs, so you can see what your adapter needs to implement.
Text-to-speech
Streaming synthesis endpoint, languages, voices, and options. Toggle Enabled to make the adapter available.
Options entered in the JSON fields are forwarded to your adapter as-is - the adapter decides what they mean.
Guardrails
Guardrails provide content safety controls for your workspace and projects. Workspace administrators can configure guardrail providers and their available scanners, while guardrail policies are configured at the project level to evaluate agent inputs and outputs against defined safety rules.- Navigation: Settings > AI Configuration > Guardrails
- Required role: Owner or Admin
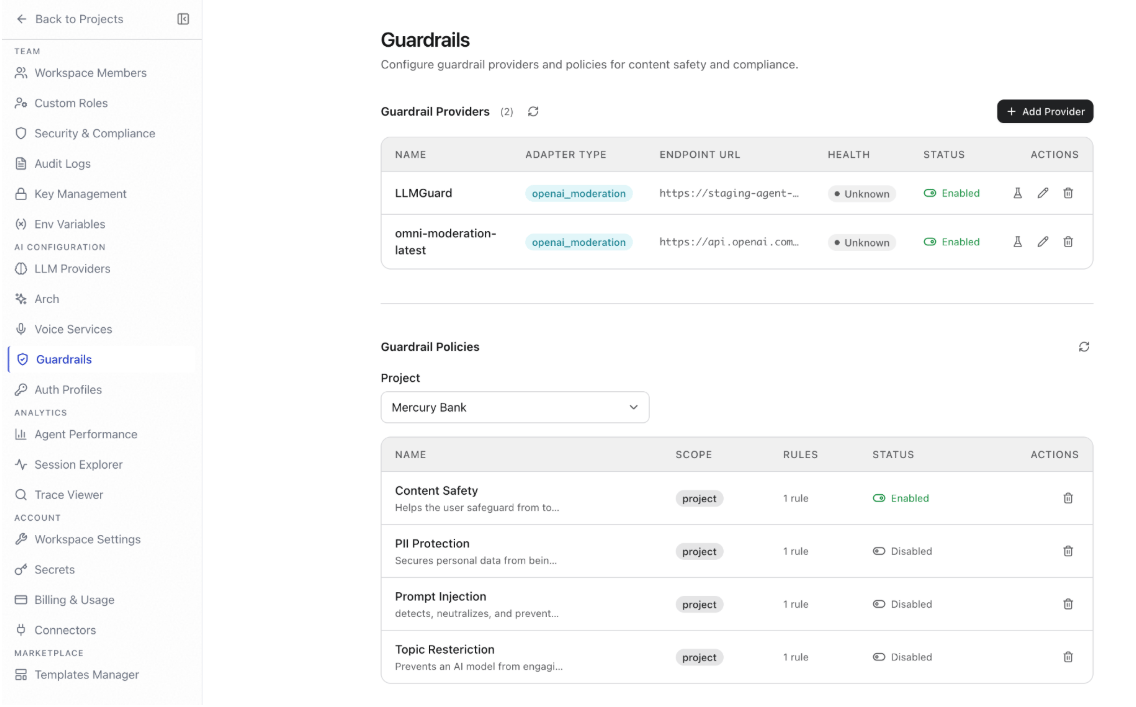
Guardrail providers
Guardrail providers are the evaluation services that assess content against your policies. Workspace administrators can add and configure guardrail providers for use across projects. Configure at least one provider before creating policies. Project authors can select which configured providers the project can use. For more information, see Select guardrail providers. Add a provider:- Go to Settings > AI Configuration > Guardrails.
- Click Add Provider.
- In the dialog, configure the provider using the Form or YAML tab.
- Click Add Provider to save.
Configure scanners
After adding a guardrail provider, workspace administrators can configure the scanners available for that provider.
- In Guardrail Providers, find the provider you want to configure.
- Click Scanners in the provider’s Actions column.
- In the Scanners panel:
- Add scanners as needed.
- Enable or disable individual scanners.
- Set the threshold for each scanner. A lower threshold is stricter and causes the scanner to trip sooner.
- Click Save scanners.
- Fail-open - Content is delivered without guardrail evaluation. Violations may go undetected.
- Fail-closed - Content is blocked until the provider recovers. Safer, but may interrupt service.
Guardrail policies
The Guardrail Policies section displays the policies configured for a selected project. Select a project from the Project dropdown to view its guardrail policies. Policies are configured at the project level and attached to guardrail providers. For information about creating and configuring guardrail policies, see Guardrail policies.Auth profiles
Auth profiles store authentication configurations that agent tools use to call external services securely. Profiles are managed centrally at the workspace level and reused across all projects.- Navigation: Settings > AI Configuration > Auth Profiles
- Required role: Owner or Admin
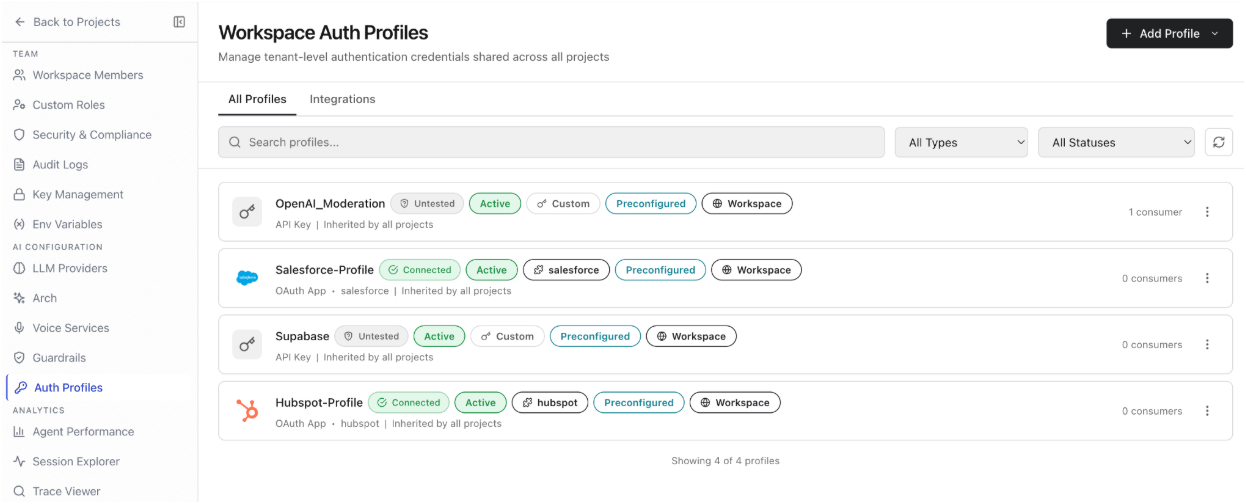
Add auth profiles
Click Add Profile. Two profile types are available:Supported auth types
Auth profile credentials are encrypted at rest and never exposed in logs or agent responses.
Guardrail providers that require credentials must reference an auth profile. Raw API keys are not accepted directly in the guardrail provider configuration.